Outbox Pattern
The outbox pattern ensures reliable message delivery by storing messages in the same database transaction as your business data, then publishing them to the message broker in a separate process. This guarantees that messages are never lost, even if the broker is temporarily unavailable.
Why Use the Outbox Pattern?
Without the outbox pattern, there's a risk of data inconsistency:
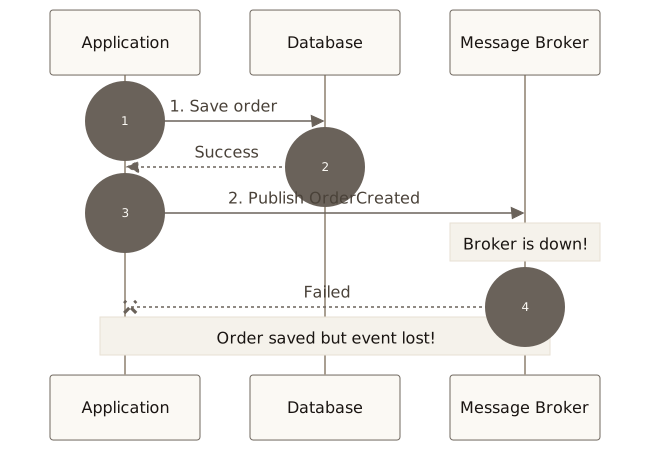
With the outbox pattern:
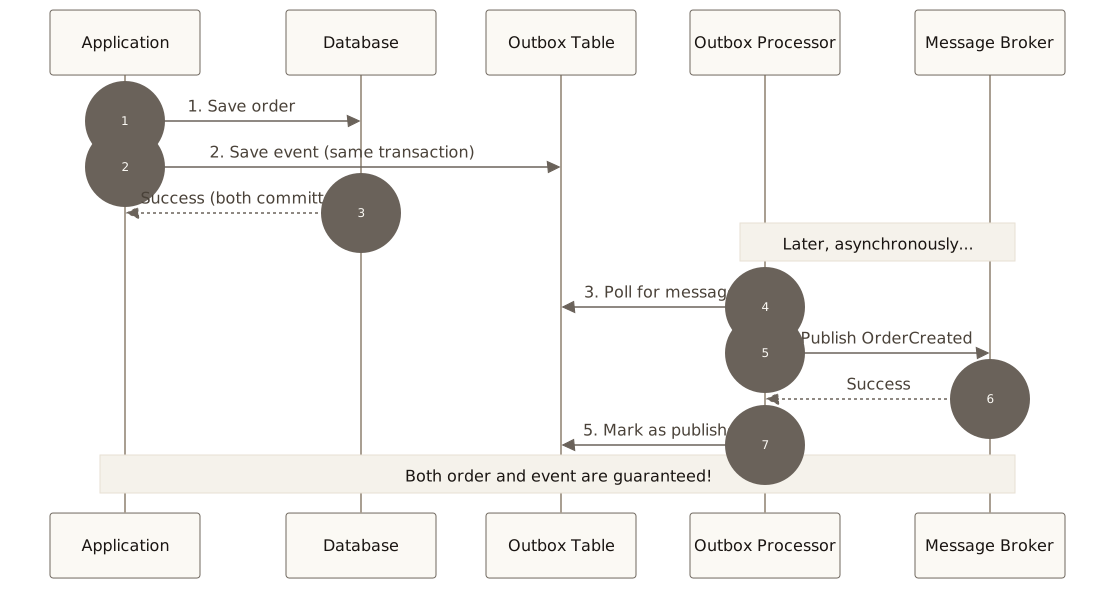
How It Works
Three things happen, in order:
1. Event storage. When an aggregate is saved through a repository, any events it raised are written to the outbox table within the same transaction as the aggregate state. If the transaction rolls back, both disappear together; if it commits, both are durable.
2. Outbox processing. The OutboxProcessor runs as part of the
Engine, polling the outbox table, publishing each row to the configured
broker, and marking the row as PUBLISHED on success. Failures are
retried with exponential backoff. Each poll pushes its status, lock-window,
and retry-window predicates into the database so a healthy outbox issues a
single SELECT per tick. When outbox.max_tick_interval is set, an idle
processor doubles its poll interval after each empty poll, up to that cap. When
a poll finds a batch, the processor returns to the base tick_interval
at once.
3. Message consumption. StreamSubscription consumers read from the broker stream, just as they would for any other message. They have no awareness of the outbox, it's an implementation detail of the publisher side.
The three steps are reliable because step 1 is transactional with the aggregate save. Steps 2 and 3 are eventually consistent but never lossy. The processor publishes each row written in the outbox at least once.
One outbox processor runs per managed database provider that an
aggregate is stored in. A provider configured with managed = false gets
none. A domain with one database has one processor; a domain with
aggregates in a default database and an analytics database has two,
each publishing its own outbox to the configured broker. When no aggregate uses
a provider, the provider gets no processor, because nothing writes to its
outbox. An example is the built-in memory provider in a domain that stores
everything in default.
See the Outbox Guide for enabling the outbox, creating the table, configuring retries and cleanup, and investigating abandoned messages.
The event store is the durable anchor
Step 1 hides one more ordering detail. A unit of work makes two durable writes to two independent datastores (the event store and the relational database) and no transaction spans both. Protean appends events to the event store first, and only then commits the relational transaction that carries aggregate state and the outbox rows. The event store, the source of truth for event-sourced replay, is the durable anchor.
This ordering trades an unrecoverable failure for a recoverable one. If the
process dies between the two writes, the events are durable in the store while
their outbox rows never committed. The events exist but would never publish.
For an event-sourced aggregate, reconciliation re-derives the missing
outbox rows from the event store. Reconciliation runs automatically on server
startup and on demand via protean outbox reconcile. Reconciliation skips a
state-based aggregate's events. A state-based aggregate's relational row is its
state. On a transactional provider that row rolled back together with the
outbox rows, so publishing the event would report a change that was never
saved. On a provider without transactions, such as Elasticsearch, the row can
be saved while its outbox row is lost, and that event stays unpublished. The
full rationale (and why this was chosen over two-phase commit) is in
ADR-0015; the
operational walkthrough is in Recover from a
crash.
External Dispatch for Published Events
Events marked with published=True can be delivered to external brokers, other bounded
contexts, partner systems, or analytics pipelines. When external_brokers is configured, the
Unit of Work creates additional outbox rows for each external broker, alongside
the internal row:
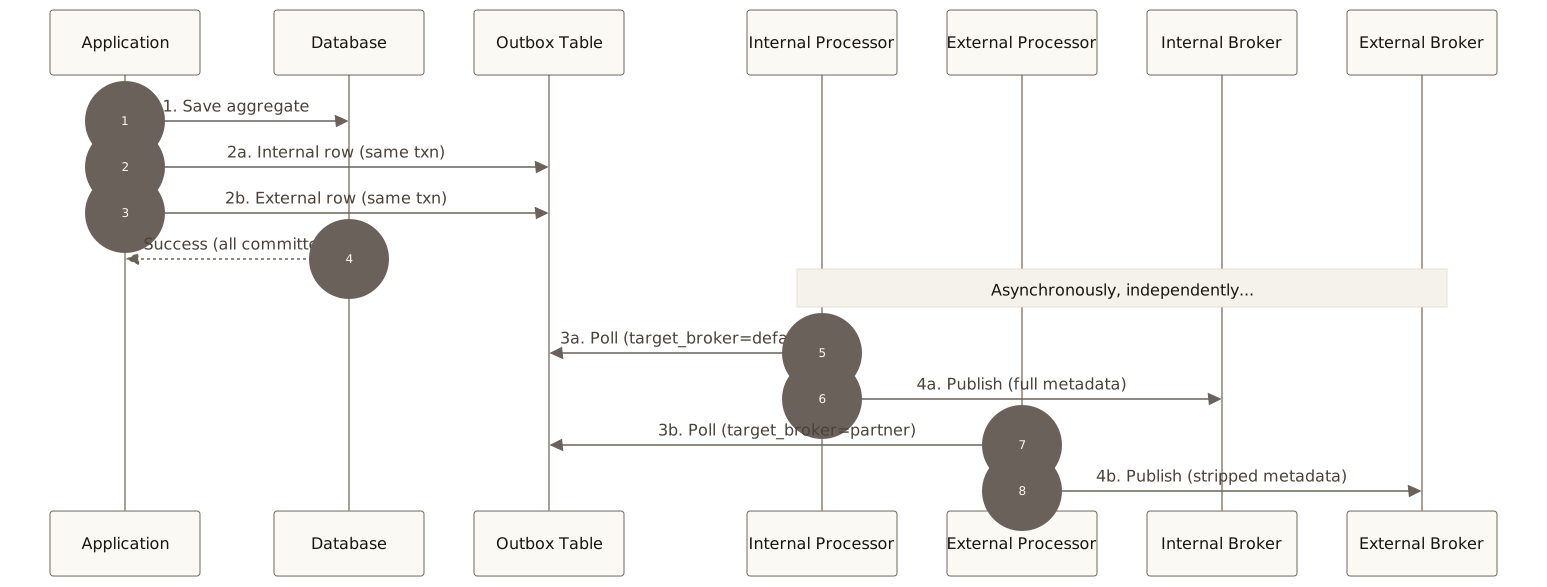
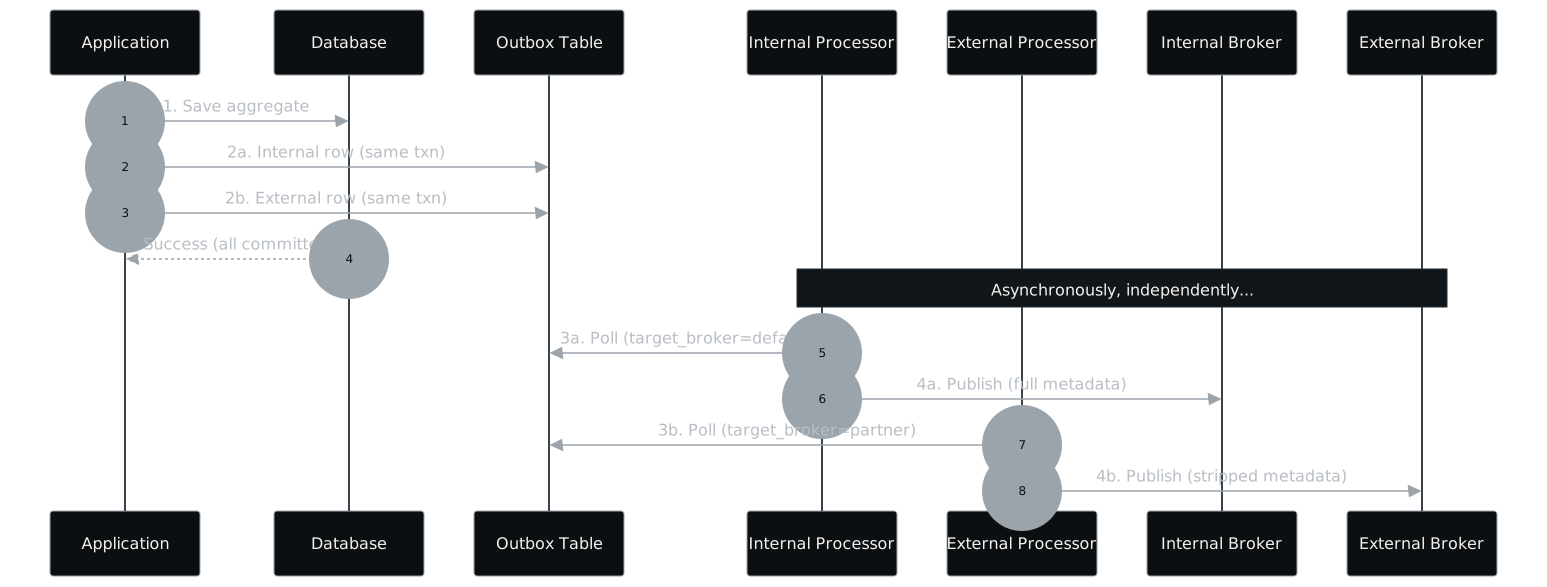
Each row is processed independently. If the external broker is down, the internal row publishes normally while the external row retries on its own schedule.
External Envelope
External messages use a stripped envelope that removes internal-only fields
(expected_version, asynchronous, priority, event store positions,
checksum). The envelope keeps the fields external consumers need: headers for
deduplication, domain context for routing, and user-provided extensions.
For setup, see Dispatching Published Events to External Brokers. For architectural trade-offs, see Publishing Events to External Brokers.
Outbox Message Lifecycle
Messages in the outbox go through several states:


Cleanup removes an abandoned row only when it has no partition key. An
abandoned row with a partition key stays in the outbox until someone retries
or discards it with protean outbox retry or protean outbox discard.
Message States
| State | Description |
|---|---|
PENDING |
Message waiting to be processed |
PROCESSING |
Message claimed by a worker |
PUBLISHED |
Successfully published to broker |
FAILED |
Publishing failed, may be retried |
ABANDONED |
Max retries exceeded, given up |
DISCARDED |
Skipped by an operator, never published, kept for audit |
Retry Mechanism
Failed messages are retried with exponential backoff:
Attempt 1: Immediate
Attempt 2: 60 seconds later (base_delay)
Attempt 3: 120 seconds later (base_delay * 2)
Attempt 4: 240 seconds later (base_delay * 4)
... up to max_backoff_seconds
With jitter enabled, delays are randomized by ±25% to prevent thundering-herd problems when a broker recovers and many messages become retry-eligible simultaneously.
After max_attempts failures, the message is marked ABANDONED and
stops retrying. It remains in the outbox table as a durable record of
the failure until cleanup removes it. Cleanup does not remove an
abandoned row with a partition key; see Message Cleanup.
For tuning retry attempts, backoff, and jitter, see the Outbox Guide.
Message Cleanup
PUBLISHED, ABANDONED and DISCARDED rows are purged on a schedule so
the outbox table doesn't grow unbounded. Published rows are kept long
enough to serve as an audit trail; abandoned and discarded rows are kept
long enough to investigate. An abandoned row with a partition key is
never purged: it holds its key's later rows, so it stays until someone
retries or discards it. You can configure the retention windows for published
rows and for abandoned and discarded rows separately. See
Outbox Guide: Configure cleanup.
Multi-Worker Support
When running with --workers N (see Multi-Worker Mode), each
worker runs its own OutboxProcessor. Messages are claimed atomically at the
database level to prevent duplicate publishing.
Database-Level Locking
The processor uses an atomic UPDATE...WHERE to claim messages. Under READ
COMMITTED isolation (PostgreSQL, MSSQL), concurrent updates on the same row
block until the first transaction commits. Each blocked update then
re-evaluates the WHERE clause, so only one worker succeeds:
from datetime import timedelta

from protean.utils.query import F, Q


def claim(dao, message, worker_id, now):
    # Simplified view of the per-message compare-and-swap inside _claim().
    # A row is eligible when it is pending, failed, or processing under an
    # expired lock, its lock is free, its retry time is due, and it has
    # retries left:
    eligible = (
        Q(id=message.id, status__in=["pending", "failed", "processing"])
        & (Q(locked_until__isnull=True) | Q(locked_until__lte=now))
        & (Q(next_retry_at__isnull=True) | Q(next_retry_at__lte=now))
        & Q(retry_count__lt=F("max_retries"))
    )
    claimed_count = dao._update_all(
        eligible,
        {
            "status": "processing",
            "locked_by": worker_id,
            "locked_until": now + timedelta(minutes=5),
            "last_processed_at": now,
        },
    )
    # claimed_count > 0 only for the winning worker
    return claimed_count
This prevents the TOCTOU (Time-Of-Check-Time-Of-Use) race condition where two
workers could both read a message as PENDING and both attempt to publish it.
Lock Fields
Each outbox message carries lock metadata:
| Field | Description |
|---|---|
locked_by |
Worker identifier that holds the lock |
locked_until |
When the lock expires (default 5 minutes) |
status |
Current processing state (PROCESSING while locked) |
Lock Lifecycle
- The worker calls
claim_batch(), which selects and claims eligible messages in one step. A message is eligible under the rules in theclaimexample above: it isPENDING,FAILEDand due for retry, orPROCESSINGunder an expired lock, and it has retries left. Through_claim(), each claim sets the status toPROCESSINGand records the worker ID and lock expiry. claim_batch()returns only the messages this worker won. A message that another worker claimed first is not in the batch.- The claim commits on its own, before any publishing starts.
- For each claimed message, the worker publishes to the broker outside any
transaction. It then records the result in a short
UnitOfWork:PUBLISHEDon success, orFAILEDfor retry when publishing failed.
Stale Lock Recovery
If a worker crashes while holding a lock, the lock expires after the configured
duration (default 5 minutes). The message remains in PROCESSING status with
an expired locked_until timestamp. Another worker detects the expired lock
and the message becomes eligible for reprocessing.
Operational Signals
Four signals characterize outbox health. Any of them drifting persistently is worth investigating:
| Signal | Meaning | Likely cause when elevated |
|---|---|---|
| Pending count | Rows waiting to be processed | Worker throughput below publish rate; broker slow or unreachable |
| Failed count | Rows that failed at least once | Transient broker errors; downstream schema drift |
| Retry rate | Fraction of attempts that retry | Persistent broker issue; publish-side bug |
| Abandoned count | Rows that exhausted retries | Chronic failure, needs investigation before cleanup removes the evidence |
Runtime visibility is available via Observatory's /api/outbox
endpoint and via direct queries on the outbox repository. See
Outbox Guide: Investigate abandoned messages.
Related
- Using the Outbox: Enable the outbox, create the table, configure retries and cleanup, investigate abandoned messages.
- Dispatching Published Events to External Brokers: Routing events to partner systems.
- Subscription Types: How StreamSubscription consumes outbox-published messages.
- Server Configuration: Full configuration reference.